Project Page · 2026
CoRL · Submission
Multisensory · Single-Pass · Real-Time Imitation

PRISM

Bridging Multimodality and Real-Time Control
in Multisensory Policies
Anonymous1
1Anonymous
§ 00  /  Method

How PRISM works — an interactive walkthrough.

Step through the pipeline at your own pace: per-timestep multisensory encoding, single-pass Performer generation, the IMLE objective, batch-global rejection, ProxyScore selection, and receding-horizon control. Scroll, use the arrow keys, or click to advance.

Robotic imitation learning typically requires policies that capture multimodal action distributions, run at real-time control rates, and accommodate multiple sensing modalities. Recent generative approaches—diffusion, flow matching, IMLE—each satisfy a subset of these requirements but not all three.

We present PRISM, a single-pass multisensory policy that meets all three by operationalizing a batch-global variant of RS–IMLE. A key technical observation: the RS–IMLE rejection mechanism, designed for few-shot image synthesis, silently fails at policy-scale batch sizes. We identify why and provide the calibration that restores it.

On real-world loco-manipulation (Unitree GO2 + 7-DoF arm) and tabletop manipulation (UR5), PRISM outperforms diffusion policies by 10–25 pp in success while sustaining 30–50 Hz closed-loop control. On CALVIN (full ABCD, language-conditioned), it improves success by ~31 pp over diffusion and ~24 pp over flow matching while reducing trajectory jerk by 20×–70×.

+31pp
Success vs. Diffusion (CALVIN, full ABCD)
70×
Lower trajectory jerk (vs. Diffusion)
50 Hz
Real-robot closed-loop control
1-pass
Single-step inference (NFE = 1)
RGB
Depth
Tactile
Proprio.
Text
Audio
§ 01  /  Real-World

Language & audio — vision-conditioned manipulation.

Four tabletop tasks executed by PRISM on a fixed-base manipulator. The policy fuses a frozen CLIP text embedding and contact-microphone audio with the visual context stream, attending to color, shape, and spatial descriptors to select the correct object and grasp.

Real-world · Language-conditioned

“Stack blue cup on green cup”

Vertical stacking with color discrimination. 92 ± 4% success across 50 trials.
RGBAudioTextProprio
Real-world · Language-conditioned

“Stack yellow cup on blue cup”

Requires reordering from initial configuration. 88 ± 5% success.
RGBAudioTextProprio
Real-world · Language-conditioned

“Put green ball in the green cup”

Shape and color matching; grasp aperture must adapt to ball geometry. 84 ± 6%.
RGBAudioTextProprio
Real-world · Language-conditioned

“Hang the green cup on the hook”

Precise spatial reasoning. 78 ± 7% success across 50 trials.
RGBAudioTextProprio
§ 02  /  Loco-Manipulation

Vision & tactile contact-rich manipulation on a quadruped.

PRISM running on a Unitree GO2 with a 7-DoF D1 arm. Tactile feedback from the gripper is fused with wrist and shoulder RGB at every timestep, enabling robust contact-rich behaviors that pure vision baselines fail to recover.

GO2 + D1 · Vision + Tactile

Multi-object pick & place

Locomotion phase + grasp + transport + release. PRISM scales from 15 to 35 demos with +30% success improvement.
Wrist RGBShoulder RGBTactileProprio
GO2 + D1 · Vision + Tactile

High-precision peg insertion

Tactile contact patterns critical for sub-mm alignment. +20% success vs. Diffusion Policy at matched demo count.
Wrist RGBShoulder RGBTactileProprio
§ 03  /  Pre-Manipulation

Whole-body parking for a 14-DoF locomotion + manipulation policy.

Before contact-rich manipulation can begin, the GO2 base must reach a stable, kinematically reachable pose. PRISM’s 14-D action space (gripper + EE pose + base linear & angular velocity) lets a single policy plan the approach end-to-end from RGB observations.

GO2 + D1 · Locomotion phase

Pre-manipulation parking — trial A

Approach phase with base locomotion: position the platform within reachable workspace before manipulation begins.
Wrist RGBShoulder RGBProprio
GO2 + D1 · Locomotion phase

Pre-manipulation parking — trial B

Alternate initial pose; the receding-horizon controller replans every Ta steps using the ProxyScore smoothness rule.
Wrist RGBShoulder RGBProprio
§ 04  /  Simulation

CALVIN benchmark — full ABCD, language-conditioned.

Trained on the full CALVIN ABCD split with language annotations, PRISM improves success by ~31 pp over Diffusion Policy and ~24 pp over Flow Matching, while reducing trajectory jerk by 20×–70×. The reel below shows representative long-horizon language-conditioned tasks executed by a single trained policy.
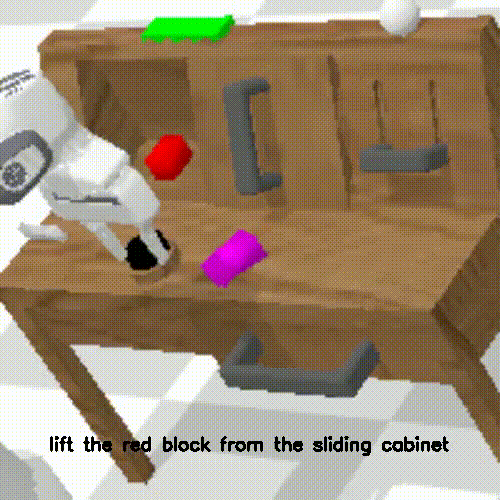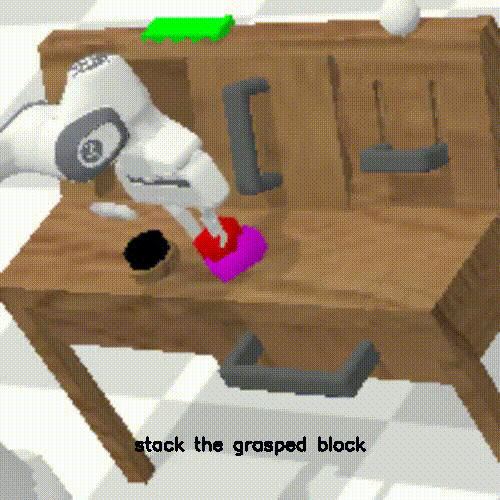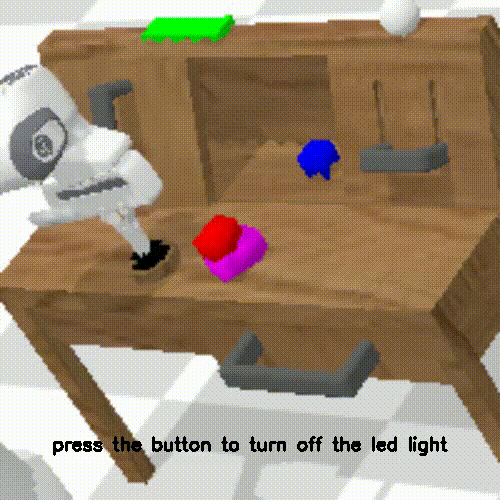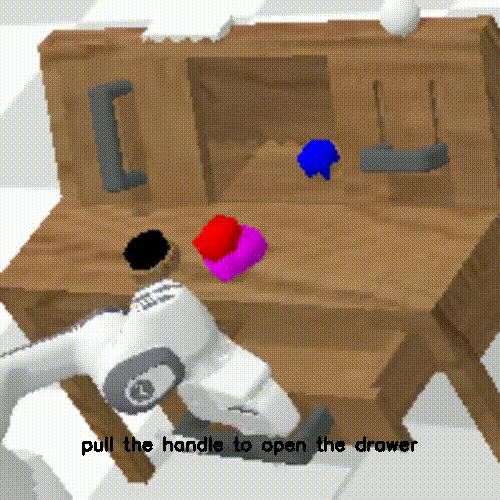
CALVIN ABCD long-horizon rollout
CALVIN (full ABCD · language-conditioned) · Simulation

Long-horizon language-conditioned rollout

Six representative tasks executed by a single PRISM policy trained on the full CALVIN ABCD split with language annotations. Wrist + static RGB, depth, tactile, and proprioception are fused per timestep. PRISM improves success by ~31 pp over Diffusion Policy and ~24 pp over Flow Matching, while reducing trajectory jerk by 20×–70×.
Static RGBWrist RGBDepthTactileProprioLanguage
§ 05  /  Citation

If you find PRISM useful, please cite.

@inproceedings{anonymous2026prism,
  title     = {{PRISM}: Bridging Multimodality and Real-Time Control in Multisensory Policies},
  author    = {Anonymous},
  booktitle = {Conference on Robot Learning (CoRL)},
  year      = {2026},
}